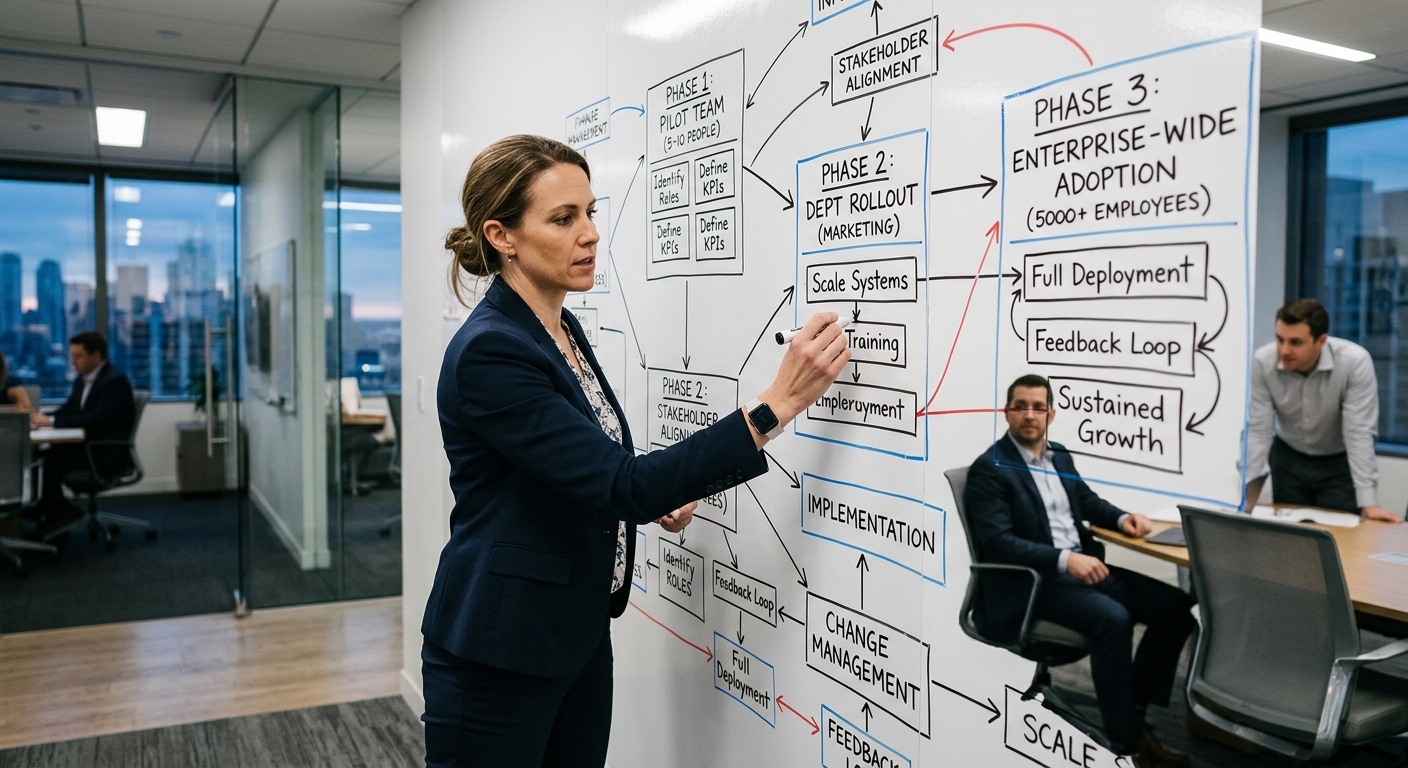
The 90-day pilot worked. Adoption metrics were strong, the use case was validated, and leadership is ready to move to enterprise-wide deployment.
This is the moment most organizations underestimate. The gap between a successful pilot and a successful rollout is where enterprise AI initiatives stall — not because the technology failed, but because the things that made the pilot work don’t automatically scale.
Here’s what breaks.
Data Access
Pilots typically run on curated data. The team preparing the pilot selects a clean, representative dataset, resolves edge cases before they surface, and operates within a permission structure that was set up specifically for the test.
At scale, the AI touches production data in all its reality: inconsistent formatting, missing fields, legacy records from ten years ago, data that sits across different systems with different permission structures. The model that performed well on pilot data will encounter inputs it wasn’t tested against, and its failure modes will surface in front of real users doing real work.
Before rollout: map the full data landscape the AI will encounter in production. The pilot dataset is a subset. Know what’s in the remainder.
Edge Cases
A well-run pilot handles the standard cases — the inputs that look like the training set, the requests that fall within the designed use case. The pilot’s success metrics reflect performance on those cases.
Enterprise-wide rollout includes everyone’s edge cases. The unusual vendor format in accounts payable. The contract clause type that appears twice a year. The support ticket from a customer describing a failure mode the system was never designed for. These inputs don’t break the AI the same way a bug breaks software — they often produce outputs that look plausible but are wrong in ways that are hard to detect.
Before rollout: define explicitly what the AI is not designed to handle. Build escalation paths for those cases before you need them.
Change Management at Scale
Pilot participants are self-selected. They volunteered, they’re interested, they’re already more tech-comfortable than the median. They give the tool genuine effort because they want it to work.
Enterprise rollout includes the full distribution: the skeptics, the people who’ve seen technology initiatives fail before, the users who have existing workflows they’re not eager to change, and the managers who didn’t ask for this and aren’t sure what to do with it.
The adoption rate in a voluntary pilot tells you almost nothing about the adoption rate in a mandatory rollout. Plan for 20–30% of users who will use the tool minimally, inconsistently, or not at all — and design the rollout to address that group specifically, not just the willing adopters.
The Users Who Won’t Adopt
Related to change management but distinct: there will be a segment of users who find ways around the AI workflow even after rollout. They’ll do the task manually, skip the AI step, or use the output without the review process you designed.
This matters because the quality of AI-assisted output in production depends on users actually following the workflow. An AI deployment where 25% of users bypass the review step has different quality characteristics than the pilot, where everyone was engaged. If you’re measuring outcome quality at the team level, adoption gaps create invisible noise in the data.
Before rollout: build workflow compliance into the measurement plan, not just adoption rate. Knowing that a tool was used is different from knowing it was used correctly.
Support and Escalation
During the pilot, the implementation team is close to the users. Questions get answered quickly, problems get triaged, feedback loops are tight. This creates a false floor — the pilot experience is higher-quality than enterprise deployment will be, because there’s dedicated attention behind it.
At scale, users need actual support structures: documentation that doesn’t require a conversation, an escalation path when the AI output is wrong in a consequential way, and a process for reporting systematic failures that gets reviewed and acted on.
Building these after the rollout is possible but expensive. Building them before is much cheaper.
Governance and Compliance
Pilots often operate in a governance gray area. They’re tests — legal, security, and compliance teams sometimes agree to look at the results after the fact. This works for pilots. It doesn’t work for production.
At scale, data governance needs to be formalized: what data the AI can access, how outputs are stored and retained, what the data residency requirements are, who is accountable for AI-assisted decisions. In regulated industries — finance, healthcare, legal — this is where rollouts stall.
The earlier these conversations happen, the faster the rollout moves. Compliance review that starts before rollout is a parallel workstream. Compliance review that starts when the rollout is already happening is a blocker.
A pilot that works is evidence that the use case is real. It is not evidence that the rollout will go smoothly. The organizations that treat them as the same problem are the ones who call us six months after the rollout asking why adoption is lower than expected and output quality is inconsistent.
VitaLink Software helps enterprise teams design AI rollouts that anticipate scale failure modes rather than react to them. Talk to us before your rollout.